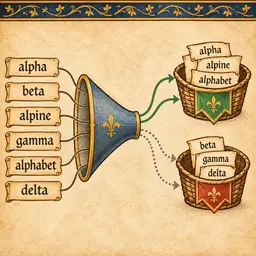
TPC-H Query 16 - Estimating String Filters
Today's TPC-H query is the first one to use a COUNT(DISTINCT).
It also contains an interesting estimation challenge.


Today's TPC-H query is the first one to use a COUNT(DISTINCT).
It also contains an interesting estimation challenge.
Today's TPC-H query is the first one to use a WITH clause.
The same expression is used twice, and the query quietly tests for a simple, yet powerful, optimisation: materialisation.
As we shall see, Databricks, Trino and DataFusion all fail the test and scan 6M more rows than the databases that implement the optimisation.
Today, we are going to learn about left and right handed joins. These joins allow the execution engine of a database to still pick the smaller side as the hash build, even when the smaller side is an outer, row preserving side.
It's easier to illustrate with an example - which brings us right to Query 13.
Today, we are going to talk about estimating filter selectivity and how to fail at it. Two queries are similar enough that we will analyse them together: Q12 and Q14.
Like listening to a song from the '80s, it is good to be back to TPC-H. I have been busy doing work with Floe. If you are a regular reader of this blog, I think you will like this article I wrote recently:
Times have been busy after joining: Floe. I highly recommend you check out our blog there to see what we are up to.
I am not giving up on my TPC-H series! Today we are half-way through the workload and have arrived at Query 11. If I am succeeding in what I set out to do, regular readers now have a good grasp on:
Today's query is pretty simple. Your new skills will let you find the optimal query plan easily.
I am going to take this chance to talk about statistics and how they relate to Query 11. We will also be talking more about bloom filters and what they can do for your analytical workload.
Welcome back to the TPC-H series, dear reader. And happy holidays to those of you who've already shut down.
In today's educational blog, I'm going to teach you about:
This is a lot of ground to cover in the around 5-15 minutes I have your attention. Every deep dive starts at the surface — let us jump into the deep sea.
Today's query will give us a new insight about about query optimisers — because one of the joins
contains a little extra surprise: Composite key joins.
We will also learn about a new, strong optimisation that we haven't seen before: Aggregating before joining.
This is the first time we encounter some series work on partsupp and its strange relationship to lineitem
Let us proceed in the familiar way.
In today's look at TPCH-H Q08, we're going to once again walk through an optimal join order example.
The query is quite boring, but it does allow me to talk about a few other things related to optimiser costing: Join Algorithms (or as some would call them: "Physical operations").
It is time to resume the TPC-H series and look at Query 7.
We will learn about how query optimisers can decompose filters and reason about the structure of expressions to reduce join work.
This query is also a good way to teach us about how query optimisers use statistics and constraints.
This is the first blog where we can now use SQL Arena to look at query plans. The SQL Arena is an ongoing project where I am using the tooling I have written to generate comparable query plans between various database engines. All the work is open source, details in the link above.
And now, for something completely different.
This week on TPC-H query analysis - we are not going to look at join ordering. Today's query does not have any joins.
But as we shall see, there is still performance to be had for a clever query optimiser.